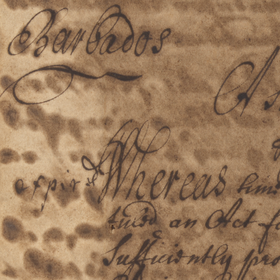
R.O.A.D. Barbados Historic Handwriting Challenge
'/%3e%3c/svg%3e)
Helping Barbados
$25 000 USD
Closing soon! (13 days left)
Optical Character Recognition
Natural Language Processing
1740 joined
574 active
Start
03 Jul 26
Close
04 Oct 26
Reveal
04 Oct 26
'%3e%3cpath fill='%23001489' d='M0 0v6h9V0z'/%3e%3cpath fill='%23e03c31' d='M0 0v3h9V0z'/%3e%3cg stroke='%23fff' stroke-width='2'%3e%3cpath id='d' d='m0 0 4.5 3L0 6m4.5-3H9'/%3e%3cuse xlink:href='%23b' stroke='%23ffb81c' clip-path='url(%23c)'/%3e%3c/g%3e%3cuse xlink:href='%23d' fill='none' stroke='%23007749' stroke-width='1.2'/%3e%3c/g%3e%3c/svg%3e)
Answering queries around pseudo-labelling
17 Aug 2026, 14:18 · 2
Transductive pseudo-labeling / self-training on the test images is allowed, provided the entire process is fully automated.
To ensure fairness and transparency across all participants, please adhere to the following mandatory rules regarding pseudo-labeling for this and future challenges:
- Fully Automated Process: The generation of pseudo-labels must be strictly algorithmic. You may use your trained models to infer labels on the test set and fold all or part of those predictions back into your training process. No manual annotations, human-in-the-loop visual transcription, or manual labeling of test images is permitted under any circumstances.
- Rules on Post-Processing: Automated post-processing rules applied to generated pseudo-labels are permitted - for example, programmatic auto-corrections based on domain logic (e.g., automatically replacing a predicted numeric 0 with the letter O in specific word contexts). However, these rules must be generalisable and code-driven, not hardcoded fixes designed to target specific individual test images observed manually.
- Code Submission & Reproducibility: If your final solution utilizes pseudo-labeling, the entire pseudo-label generation pipeline (including inference, post-processing logic, and re-training loops) must be clearly explained in your solution documentation and fully reproducible via your submitted code.
are we allowed to tinker with train dataset? manual labeling on train dataset?
NO I DO NO THINK SO