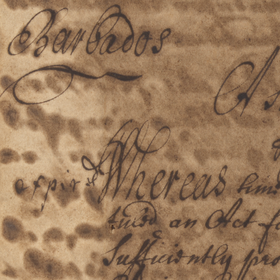
R.O.A.D. Barbados Historic Handwriting Challenge
'/%3e%3c/svg%3e)
Helping Barbados
$25 000 USD
Closing soon! (3 days left)
Optical Character Recognition
Natural Language Processing
1984 joined
749 active
Start
03 Jul 26
Close
04 Oct 26
Reveal
05 Oct 26

OCR models, VLM, or custom?
9 Aug 2026, 11:09 · 4
Hi everyone! I have a question for folks who broke above .91, I am not looking for exact setups, just curious about the general direction people went. Are you mostly using OCR-specific models, general-purpose VLMs, or fully custom-trained architectures? Even a rough breakdown would help. Thanks
@sdv I would appreciate your take on this :)
I am slightly above 91. I did qwen + lora + grpo and beam search. However, I think some of the data might be bad and I shouldn't use all the data
Thanks!! May I ask what was the score without GRPO?
you mean u got 0.9 with the data itself !!?? -- without making a code that cleans and analyze the images and data !!? dude ... images are very dirty ... u need to find a solution for that first... ull hit 0.96 of u really did submit a csv with the dirty data ...