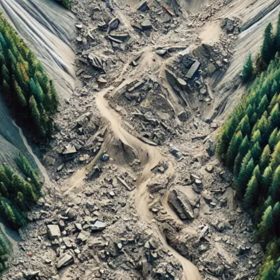
Classification for Landslide Detection by ITU
1 000 CHF
Completed (~1 year ago)
Classification
Earth Observation
Python
GIS
Computer Vision
Machine Learning
Deep Learning
1028 joined
303 active
Start
17 Apr 25
Close
04 Aug 25
Reveal
04 Aug 25
'%3e%3cg id='b'%3e%3cpath id='a' d='M0-8v8h4z' transform='rotate(18 0 -8)'/%3e%3cuse xlink:href='%23a' transform='scale(-1 1)'/%3e%3c/g%3e%3cuse xlink:href='%23b' transform='rotate(72)'/%3e%3cuse xlink:href='%23b' transform='rotate(144)'/%3e%3cuse xlink:href='%23b' transform='rotate(216)'/%3e%3cuse xlink:href='%23b' transform='rotate(288)'/%3e%3c/g%3e%3c/svg%3e)
Huge dissimilarity between train and test set? Great CV score, but poor leaderboard result
Data · 26 Jul 2025, 14:56 · 5
I'm achieving F1-scores above 0.90 on the training set using cross-validation, but my score drops drastically on the public leaderboard after submission.
It makes me strongly suspect a huge dissimilarity between the train and test sets: different distributions, class imbalance, covariate shift, or even label inconsistencies.
Has anyone faced something similar in a competition? How can I detect and mitigate this train-test mismatch?
PS: I’m using stratified K-Fold CV, and I’ve tried techniques like SMOTE, class weighting, threshold tuning per fold, etc. Nothing seems to bridge the gap.
Franchement, j’ai l’impression que le test set vient d’un autre monde 😅
What's your LB score?
0.83
Have you tried ensembling separate models
No, I think there's a huge LB to CV correlation. Might just be off by some decimals. I think you might be overfitting if you are using a computer vision approach.
My CV and learderboard score also correlate pretty well.
However, one thing I am almost sure about, is that the class imbalance is even stronger in the test set. In case you assume the ratio between classes to be the same you might run into some misguided results